DataOps Strategies for Modern Data Engineering: Best Practices and Benefits
 Mohammad Nabi 30 min read
Data has become one of the most valuable business assets. Organizations rely on it to understand customer behavior, monitor business performance, improve operational efficiency, develop AI applications, and make informed decisions. However, managing large volumes of data across multiple systems is becoming increasingly complex.
Traditional data engineering approaches often involve disconnected tools, manual processes, inconsistent data quality checks, and time-consuming pipeline deployments. These challenges can slow down data delivery, create operational bottlenecks, and make it difficult for businesses to trust their data.
This is where DataOps comes into the picture.
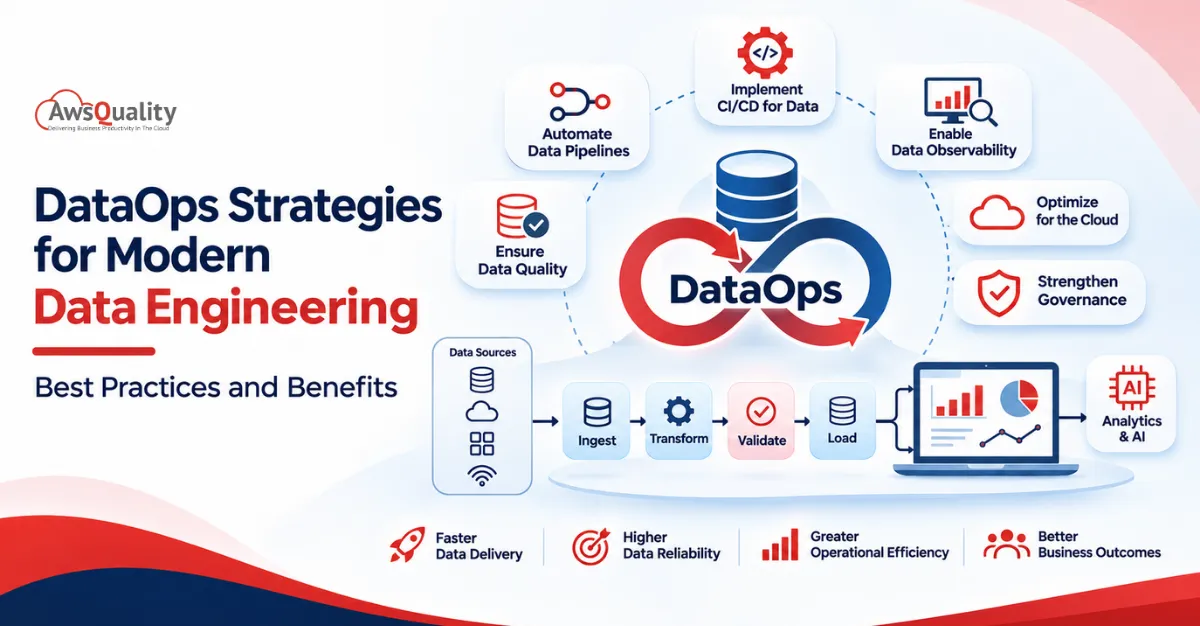
DataOps brings automation, collaboration, continuous integration, testing, monitoring, and governance practices into the data engineering lifecycle. It helps organizations build more reliable data pipelines, improve data quality, reduce manual intervention, and deliver business-ready data faster.
As businesses adopt cloud data platforms, real-time analytics, and AI-driven applications, implementing effective DataOps strategies is becoming increasingly important.
But what exactly is DataOps, and how can organizations apply it to modern data engineering?
In this guide, we explore the key DataOps strategies, best practices, tools, implementation steps, and business benefits that can help organizations build scalable and efficient data engineering environments.
What is DataOps?
DataOps, short for Data Operations, is a collaborative approach to managing and improving the data lifecycle by combining principles from Agile development, DevOps, data management, and automation.
It focuses on making data workflows more efficient, reliable, repeatable, and scalable through practices such as continuous integration and delivery (CI/CD), automated data testing, workflow orchestration, data quality management, and continuous monitoring.
In traditional data engineering environments, teams often work in separate functions. Data engineers build pipelines, analysts prepare reports, data scientists develop models, and operations teams manage infrastructure. This separation can create communication gaps, delays, and inconsistencies.
DataOps brings these activities together through standardized processes and shared responsibilities.
For example, consider a retail company that collects data from its e-commerce platform, CRM, inventory management system, and payment gateway.
Without DataOps, data engineers may need to manually extract, clean, transform, and validate information before making it available to analytics teams.
With a DataOps approach, the organization can automate these activities:
- Collect data from different business applications.
- Validate incoming data for accuracy and completeness.
- Transform and standardize records.
- Run automated tests to identify inconsistencies.
- Load validated data into a data warehouse or lakehouse.
- Monitor pipeline performance and data freshness.
- Make trusted data available to dashboards, analytics, and AI applications.
This approach reduces manual intervention and helps teams deliver reliable data more consistently.
In simple terms, DataOps applies software engineering and operational best practices to the data lifecycle so businesses can deliver trustworthy data faster.
Read: How to Reduce Data Engineering Technical Debt
DataOps vs. Traditional Data Engineering
Traditional data engineering and DataOps share many activities, but they differ in how workflows are developed, managed, tested, and maintained.
| Area | Traditional data engineering | DataOps approach |
|---|---|---|
| Development | Often relies on manual processes | Uses automated and repeatable workflows |
| Testing | Testing may happen at specific stages | Continuous and automated testing |
| Deployment | Manual or scheduled deployments | CI/CD-driven deployments |
| Collaboration | Teams may work in silos | Cross-functional collaboration |
| Data quality | Periodic validation | Continuous data quality checks |
| Monitoring | Basic pipeline monitoring | End-to-end observability |
| Version control | May focus mainly on code | Tracks code, configurations, and relevant data assets |
| Issue resolution | Often reactive | Proactive monitoring and automated alerts |
DataOps does not replace data engineering. Instead, it improves how data engineering teams develop, deploy, operate, and maintain data pipelines.
Why is DataOps Important for Modern Data Engineering?
Modern businesses generate data from an expanding range of sources, including websites, mobile applications, IoT devices, enterprise software, cloud platforms, and third-party services.
Managing these data sources manually becomes difficult as data volumes, processing requirements, and business expectations increase.
DataOps helps organizations address these challenges by introducing automation, standardization, and continuous quality management throughout the data lifecycle.
Here are some reasons why DataOps is becoming an important part of modern data engineering.
1. Increasing Data Complexity
Businesses frequently operate across multiple databases, cloud environments, applications, and data platforms.
Data engineers must collect and combine information from different sources while maintaining consistency.
DataOps helps standardize data ingestion, transformation, validation, and deployment processes, making complex data environments easier to manage.
2. Growing Demand for Real-Time Data
Many business decisions depend on timely information.
For example, financial organizations need to monitor transactions, retailers want visibility into inventory levels, and logistics companies track shipments and delivery activities.
DataOps supports automated and continuously monitored data workflows that can accommodate batch and streaming architectures.
3. Higher Expectations for Data Quality
Incorrect, incomplete, or outdated data can affect business reporting, customer experiences, and operational decisions.
DataOps introduces automated validation and testing at different pipeline stages, helping teams identify problems before they reach downstream applications.
4. Increasing Adoption of AI and Machine Learning
AI and machine learning applications depend on reliable, accessible, and well-prepared data.
Organizations need consistent data ingestion, transformation, validation, and monitoring to maintain dependable AI workflows.
DataOps helps establish these foundations and complements MLOps practices for managing machine learning models and their lifecycle.
5. Pressure to Reduce Operational Costs
Manual data preparation, troubleshooting, and deployment activities consume engineering resources.
By automating repetitive tasks and standardizing workflows, DataOps can reduce operational overhead and improve engineering productivity.
Organizations can then allocate more resources to analytics, innovation, and business improvement initiatives.
Also read: A Complete Guide to Scaling DevOps Across Large Organizations
Key Components of a DataOps Framework
A successful DataOps strategy requires more than implementing automation tools. It needs a structured framework that connects people, processes, technology, and governance.
The following components form the foundation of an effective DataOps framework.
1. Data Pipeline Automation and Orchestration
Data pipeline automation reduces manual effort involved in collecting, processing, transforming, and delivering data.
Orchestration tools coordinate different pipeline activities, manage dependencies, schedule workflows, and handle execution failures.
For example, an automated pipeline may:
- Extract customer data from CRM systems.
- Load raw information into a cloud data lake.
- Transform records into standardized formats.
- Validate data against predefined rules.
- Load processed data into a warehouse.
- Refresh business intelligence dashboards.
Tools such as Apache Airflow, AWS Step Functions, and other workflow orchestration platforms can support these activities.
2. Continuous Integration and Continuous Delivery (CI/CD)
CI/CD applies software development practices to data engineering workflows.
It helps teams automatically validate, test, and deploy changes to data pipelines and transformation logic.
For example, when a developer updates a data transformation script, a CI pipeline can automatically:
- Detect the code change.
- Run code quality checks.
- Execute automated tests.
- Validate dependencies and configurations.
- Prepare the deployment package.
- Promote approved changes to the next environment.
This reduces the risks associated with manual deployments and helps teams release pipeline improvements more frequently.
3. Automated Data Quality Testing
Data quality management ensures that information meets defined standards before it is consumed by business applications.
Common data quality dimensions include:
- Accuracy
- Completeness
- Consistency
- Validity
- Uniqueness
- Timeliness
For example, an e-commerce company may validate that every order record contains a valid order ID, customer ID, transaction date, and order amount.
Automated tests can identify missing values, duplicate records, unexpected data types, and invalid entries.
Tools such as Great Expectations, Soda, and dbt tests can help implement data quality checks.
4. Data Observability and Monitoring
Monitoring helps teams understand whether pipelines are running successfully. Data observability goes further by helping them investigate why data issues occur and how they affect downstream systems.
Important monitoring areas include:
- Pipeline execution status
- Data freshness
- Data volume changes
- Schema changes
- Processing delays
- Failed tasks
- Data quality anomalies
- Resource utilization
For example, if a daily sales pipeline normally processes 500,000 records but suddenly receives only 50,000, an observability system can flag the unexpected change and alert the responsible team.
5. Version Control and Reproducibility
Version control allows data engineering teams to track changes to code, transformation logic, configuration files, and infrastructure definitions.
Using Git-based workflows helps developers collaborate, review changes, maintain release history, and roll back problematic deployments.
For greater reproducibility, organizations should also consider how they version datasets, schemas, transformation dependencies, and relevant metadata.
6. Data Governance and Security
Data governance establishes the policies and responsibilities required to manage information throughout its lifecycle.
A DataOps framework should include:
- Role-based access controls
- Data classification
- Metadata management
- Data lineage
- Encryption
- Audit logging
- Retention policies
- Compliance controls
Governance should be integrated into data workflows rather than treated as a separate activity performed only after deployment.
7. Cross-Functional Collaboration
DataOps requires collaboration between data engineers, analysts, data scientists, DevOps engineers, security teams, and business stakeholders.
Each group should understand how its activities affect the broader data lifecycle.
Shared standards, documentation, code reviews, and feedback processes help reduce communication gaps and improve delivery consistency.
Check: Cloud Data Engineering – Best Practices for Enterprise Success
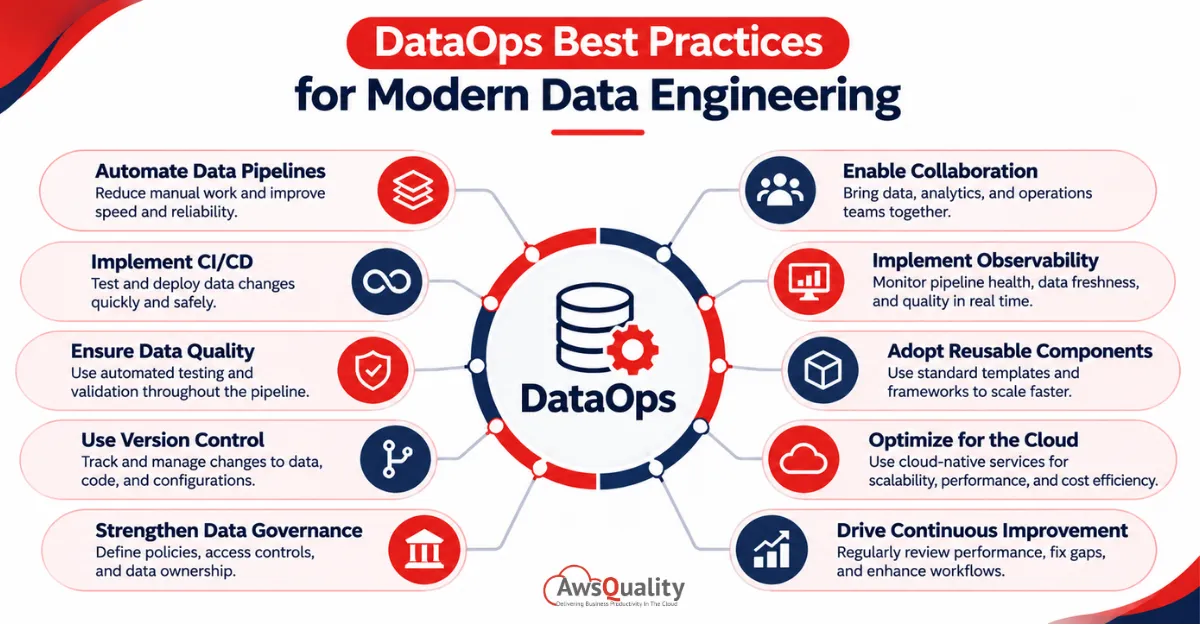
10 Essential DataOps Strategies for Modern Data Engineering
Implementing DataOps successfully requires a practical strategy that addresses the entire data lifecycle, from ingestion to consumption.
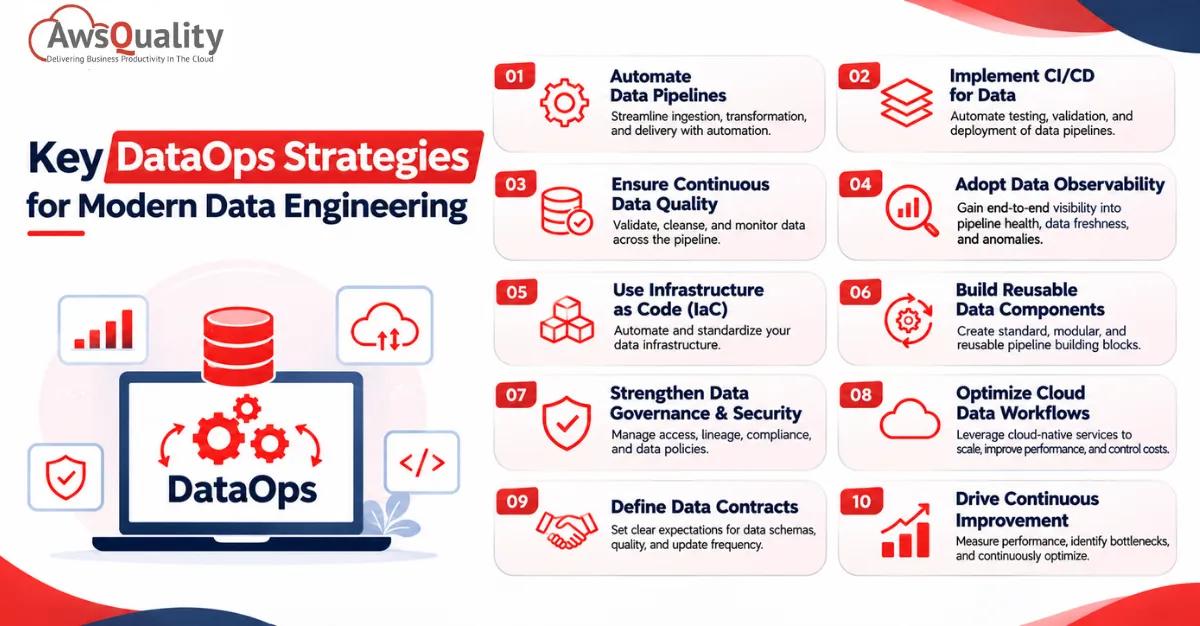
Here are ten DataOps strategies businesses can adopt to improve their modern data engineering environments.
1. Automate End-to-End Data Pipelines
One of the most important DataOps strategies is to automate repetitive activities throughout the data pipeline.
Manual data extraction, transformation, validation, and loading can become difficult to manage as data volumes increase.
Automation helps standardize these activities and reduce the likelihood of human error.
Organizations should identify repetitive workflows and gradually automate:
- Data ingestion from multiple sources
- ETL and ELT processing
- Data transformation
- Data validation
- Pipeline scheduling
- Data loading
- Error notifications
- Workflow recovery
Practical example:
A financial services company receives transaction data from multiple payment systems. Instead of manually consolidating records, it can automate ingestion, validation, deduplication, and transformation before loading the information into its analytics platform.
The result is a more consistent data processing workflow with less manual intervention.
2. Implement CI/CD for Data Pipelines
Data pipelines change as business requirements, data sources, and transformation rules evolve.
Without proper release management, even a small code change can affect downstream reports, dashboards, or applications.
Implementing CI/CD helps data teams manage these changes in a controlled and repeatable way.
A practical CI/CD workflow for data engineering includes:
- Developers create or update pipeline code.
- Changes are committed to a version control repository.
- Automated checks and tests run.
- Failed tests prevent the change from progressing.
- Approved changes are deployed to staging.
- Integration and data validation checks are completed.
- The release is promoted to production.
Use separate development, staging, and production environments wherever appropriate.
This strategy helps improve deployment consistency and makes it easier to identify issues before they affect business users.
3. Make Data Quality Testing a Continuous Process
Data quality should not be checked only after information reaches the warehouse.
Instead, validation should happen throughout the pipeline.
Organizations should define data quality rules based on how the information will be used.
For example:
| Data quality dimension | Example validation rule |
|---|---|
| Completeness | Customer email cannot be empty when required |
| Accuracy | Transaction amount must follow business rules |
| Uniqueness | Order ID must not contain duplicates |
| Validity | Transaction date must follow the expected format |
| Consistency | Customer identifiers must match across systems |
| Timeliness | Daily sales data must arrive within the agreed window |
Automated testing frameworks can execute these checks whenever data is ingested or transformed.
Teams should also define what happens when a validation fails. Depending on the severity, the pipeline may reject records, quarantine them, issue an alert, or stop downstream processing.
4. Adopt Data Observability for Proactive Monitoring
A pipeline can complete successfully while still delivering incorrect or incomplete information.
For example, a sales pipeline may execute without errors but process only a fraction of the expected transactions.
This is why monitoring execution status alone is not sufficient.
Data observability helps teams monitor the health and behavior of data as it moves through the system.
Implement monitoring for:
- Data freshness and availability
- Record volume variations
- Schema changes
- Data distribution anomalies
- Pipeline execution duration
- Failed transformations
- Downstream dependencies
Set alerts based on business impact rather than sending notifications for every minor technical event.
For example, a delay in a critical financial reporting pipeline may require immediate escalation, while a delay in a non-critical historical data refresh may have a lower priority.
5. Use Infrastructure as Code (IaC)
Infrastructure as Code allows organizations to define and manage infrastructure through version-controlled configuration files.
Instead of manually configuring data processing environments, teams can use tools such as Terraform, AWS CloudFormation, or similar technologies to automate infrastructure provisioning.
IaC can help standardize:
- Cloud storage resources
- Data processing environments
- Networking configurations
- Access permissions
- Monitoring infrastructure
- Pipeline execution environments
This improves consistency across development, testing, and production environments.
It also makes infrastructure changes easier to review, reproduce, and audit.
6. Standardize Data Pipelines With Reusable Components
When every data engineering team develops pipelines differently, organizations often end up with inconsistent naming conventions, duplicate code, and difficult maintenance processes.
A better approach is to create reusable pipeline templates and shared engineering standards.
These may include:
- Standard ingestion patterns
- Reusable transformation functions
- Common data validation rules
- Standard error-handling mechanisms
- Shared logging and monitoring configurations
- Consistent deployment templates
For example, if multiple teams regularly ingest data from REST APIs, they can use a shared ingestion framework rather than building a separate solution for every source.
Reusable components reduce duplication and help teams maintain consistency as the data environment grows.
7. Strengthen Data Governance and Security
DataOps should integrate governance and security throughout the data engineering lifecycle.
Organizations must understand what information they collect, where it is stored, who can access it, and how it is processed.
Important practices include:
- Implementing role-based access controls.
- Encrypting sensitive data at rest and in transit.
- Using secure secrets management.
- Tracking data lineage.
- Classifying sensitive information.
- Maintaining audit logs.
- Applying retention and deletion policies.
- Reviewing permissions regularly.
Organizations handling personal, financial, or regulated information should also align their DataOps processes with applicable compliance requirements.
8. Optimize Cloud-Based Data Engineering Workflows
Many organizations use cloud platforms to store, process, and analyze large datasets.
However, inefficient resource allocation, unnecessary processing, and poorly designed pipelines can increase infrastructure costs.
Cloud-focused DataOps strategies should include:
- Automating resource provisioning.
- Selecting appropriate storage and compute services.
- Optimizing data partitioning.
- Reducing unnecessary data movement.
- Monitoring cloud resource utilization.
- Scheduling non-critical workloads efficiently.
- Using serverless processing where appropriate.
For example, an organization running periodic analytics workloads may benefit from automatically scaling compute resources based on processing demand instead of maintaining oversized infrastructure throughout the day.
AwsQuality’s Cloud Services capabilities can be relevant when organizations need support designing and optimizing cloud-based data engineering environments.
9. Introduce Data Contracts Between Producers and Consumers
Data contracts define expectations between the teams or systems that produce data and those that consume it.
They can specify:
- Expected data schemas
- Field definitions
- Data types
- Required fields
- Quality expectations
- Update frequency
- Compatibility requirements
- Ownership and responsibilities
For example, an e-commerce application may publish an order dataset containing order ID, customer ID, order date, and transaction amount.
The analytics team depends on this structure to generate sales reports.
If the application team changes a field name or data type without notifying downstream consumers, reports and pipelines may break.
A data contract helps establish expectations and provides a process for managing changes.
10. Build a Culture of Continuous Improvement
DataOps is not a one-time technology implementation. It requires continuous evaluation and improvement.
Data teams should regularly review pipeline performance, deployment processes, data quality, operational costs, and stakeholder feedback.
Useful questions include:
- Which pipelines experience frequent failures?
- Where do manual processes still exist?
- Which data quality issues occur repeatedly?
- Are deployments taking longer than expected?
- Are cloud resources being used efficiently?
- Are business users receiving data on time?
Use these insights to prioritize improvements and measure their impact.
This helps organizations build a sustainable DataOps practice that evolves alongside business requirements.
DataOps Tools and Technologies for Modern Data Engineering
Choosing the right tools is an important part of building a successful DataOps environment. Organizations need technologies that support data ingestion, transformation, orchestration, testing, monitoring, version control, and deployment.
There is no single tool that covers every DataOps requirement. The right technology stack depends on data volume, architecture, cloud environment, team expertise, integration requirements, and budget.
Here are some commonly used technologies across the modern DataOps ecosystem.
| Tool / Technology | Primary purpose | How it supports DataOps |
|---|---|---|
| Apache Airflow | Workflow orchestration | Schedules and manages data pipeline dependencies |
| dbt | Data transformation and testing | Supports version-controlled transformations and automated tests |
| Apache Spark | Distributed data processing | Processes large datasets across distributed environments |
| Great Expectations | Data quality testing | Defines and validates expectations about data |
| Soda | Data quality and monitoring | Detects data quality issues |
| Git | Version control | Tracks changes to pipeline code and configurations |
| Jenkins | CI/CD automation | Automates testing and deployment workflows |
| Terraform | Infrastructure as Code | Automates infrastructure provisioning |
| Databricks | Data engineering and analytics | Supports large-scale data processing and lakehouse workflows |
| Snowflake | Cloud data platform | Supports data storage, processing, and analytics |
Also check: Top Data Engineering Trends Every Business Should Know
Cloud Platforms Supporting DataOps
Cloud platforms provide infrastructure and managed services for building scalable data engineering environments.
Amazon Web Services (AWS): Services such as Amazon S3, AWS Glue, Amazon Redshift, Amazon Kinesis, and AWS Step Functions can support data storage, processing, streaming, and orchestration.
Microsoft Azure: Azure Data Factory, Azure Databricks, and Microsoft Fabric provide capabilities for data integration, transformation, processing, and analytics.
Google Cloud Platform (GCP): BigQuery, Dataflow, Pub/Sub, and Cloud Composer support data warehousing, stream processing, messaging, and workflow orchestration.
Organizations should select tools based on their actual requirements rather than adopting technologies simply because they are popular. A smaller, well-integrated toolchain is often easier to operate than a large collection of overlapping platforms.
How to Implement DataOps in Your Organization: A Step-by-Step Approach
Understanding DataOps strategies is only the beginning. Organizations also need a practical implementation roadmap that considers existing infrastructure, business requirements, team capabilities, and long-term goals.
The following steps provide a structured approach to implementing DataOps.
Step 1: Assess Your Existing Data Engineering Environment
Start by evaluating how your organization currently collects, processes, stores, and uses data.
Identify:
- Existing data sources and applications
- Data warehouses, lakes, and databases
- Current ETL and ELT pipelines
- Manual data processing activities
- Data quality issues
- Deployment procedures
- Monitoring and reporting capabilities
- Security and governance requirements
This assessment helps identify operational bottlenecks and areas where automation can deliver the greatest value.
Step 2: Define Business Goals and Success Metrics
DataOps should support measurable business outcomes rather than focus exclusively on technical improvements.
For example, your organization may want to:
- Reduce pipeline deployment time.
- Improve data freshness.
- Reduce data quality incidents.
- Increase pipeline reliability.
- Reduce manual engineering effort.
- Improve the availability of analytics-ready data.
Define measurable KPIs before implementation so the team can evaluate progress.
Step 3: Design the DataOps Architecture
Create an architecture that connects data sources, ingestion systems, transformation tools, storage platforms, testing frameworks, and monitoring solutions.
Consider the following requirements:
- Batch and streaming data processing
- Cloud or hybrid infrastructure
- Data integration patterns
- Pipeline orchestration
- Automated testing
- Version control
- Security and governance
- Monitoring and alerting
Choose technologies that integrate well with your existing systems and can support future business requirements.
Step 4: Establish Version Control and CI/CD Workflows
Move pipeline code, transformation logic, infrastructure configurations, and deployment scripts into version control wherever appropriate.
Set up CI/CD workflows to automatically execute code reviews, validation checks, and deployment activities.
Start with a small number of critical pipelines before expanding automation across the environment.
Step 5: Introduce Automated Data Quality Checks
Define data quality rules for critical datasets and implement automated validation throughout the pipeline.
Prioritize important business information such as customer records, financial transactions, inventory, and sales data.
Create clear procedures for handling failed validations, including alerts, quarantine processes, retries, and escalation.
Step 6: Implement Monitoring and Observability
Establish visibility into pipeline execution, data freshness, schema changes, processing volumes, and data quality.
Configure alerts based on business impact and assign ownership for investigating issues.
Make sure teams can trace failures to their source and understand which downstream reports, applications, or analytics workflows are affected.
Step 7: Establish Data Governance and Team Responsibilities
Define ownership for datasets, pipelines, infrastructure, security, and quality standards.
Establish access policies, documentation requirements, data lineage practices, and change management procedures.
Ensure that business stakeholders and technical teams understand their responsibilities.
Step 8: Start With a Pilot Project
Instead of changing every data pipeline at once, select a high-value workflow for the initial DataOps implementation.
For example, you could automate the ingestion and validation of customer data from CRM and e-commerce systems.
Use the pilot to evaluate:
- Automation effectiveness
- Testing coverage
- Deployment reliability
- Data quality improvements
- Monitoring capabilities
- Team adoption
Document lessons learned before expanding the approach.
Step 9: Scale and Continuously Improve
Once the pilot demonstrates value, gradually extend DataOps practices to additional pipelines, teams, and data platforms.
Standardize reusable components, improve automation, refine monitoring, and regularly review performance metrics.
A phased rollout helps organizations manage complexity while developing a sustainable DataOps operating model.
Also check: From Data Silos to Business Insights – How Data Engineering Creates Enterprise Value
Key Benefits of DataOps for Modern Businesses
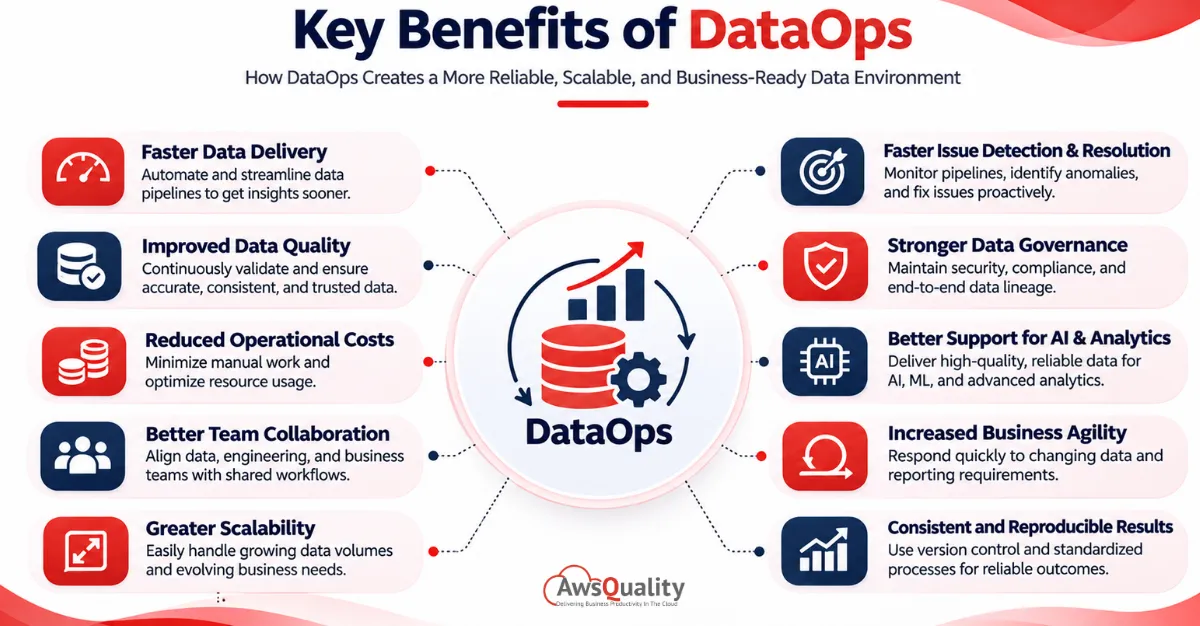
Implementing DataOps can improve the way organizations manage and deliver data. By combining automation, collaboration, testing, and continuous monitoring, businesses can establish more reliable data engineering operations.
Here are some of the major benefits.
1. Faster Data Delivery
Automated ingestion, transformation, testing, and deployment processes reduce manual handoffs and repetitive tasks.
This helps organizations make analytics-ready data available to business users more efficiently.
2. Improved Data Quality and Reliability
Continuous validation and automated testing help identify incomplete, inconsistent, or inaccurate information before it affects downstream systems.
This increases confidence in reports, dashboards, and analytical outputs.
3. Reduced Operational Costs
Automation reduces the effort required for routine pipeline development, testing, deployment, and troubleshooting.
Organizations can also optimize cloud resources and reduce unnecessary data processing.
4. Better Collaboration Between Teams
DataOps encourages collaboration between data engineers, analysts, data scientists, DevOps teams, and business stakeholders.
Shared workflows, standards, and responsibilities help reduce communication gaps and improve delivery consistency.
5. Greater Scalability
Reusable pipeline components, automated infrastructure provisioning, and standardized deployment processes make it easier to support growing data volumes and additional business requirements.
6. Faster Issue Detection and Resolution
Monitoring, logging, and observability help teams detect pipeline failures, unexpected data changes, and processing delays.
This enables more proactive troubleshooting and reduces the time required to investigate problems.
7. Stronger Data Governance and Security
Integrating governance controls into data workflows helps organizations manage access, monitor data usage, maintain lineage, and enforce security requirements.
8. Better Support for AI and Advanced Analytics
AI and machine learning applications depend on reliable data pipelines and well-managed datasets.
DataOps helps organizations establish the data quality, accessibility, and operational consistency needed to support these initiatives.
9. Improved Business Agility
With automated and repeatable data workflows, organizations can respond more quickly to changing reporting requirements, new data sources, and emerging business opportunities.
10. More Consistent and Reproducible Results
Version-controlled pipelines, documented transformations, standardized environments, and repeatable testing help teams reproduce results and investigate historical changes.
These benefits are interconnected. For example, better testing can reduce pipeline failures, while improved observability can help teams resolve the remaining failures faster.
Read: Data Lake vs Data Warehouse vs Lakehouse – Which is Right for Your Business?
Common DataOps Challenges and How to Overcome Them
Although DataOps offers significant advantages, implementing it across an organization can introduce technical and operational challenges.
Understanding these challenges early helps businesses prepare a more realistic implementation strategy.
| Challenge | Why it matters | Recommended approach |
|---|---|---|
| Legacy infrastructure | Older systems may not support modern automation easily | Modernize incrementally and use appropriate integration patterns |
| Data silos | Information remains fragmented across departments | Establish standardized data integration and ownership |
| Poor data quality | Inaccurate information affects downstream analytics | Implement continuous data validation |
| Tool complexity | Too many disconnected tools increase maintenance effort | Adopt a carefully selected, integrated toolchain |
| Skills gaps | Teams may lack experience with CI/CD and data observability | Invest in training and specialist expertise |
| Governance challenges | Unclear ownership creates security and compliance risks | Define governance policies and responsibilities |
| Integration issues | Changes in source systems can disrupt pipelines | Introduce data contracts and integration testing |
| Organizational resistance | Teams may be reluctant to change established workflows | Use pilot projects and demonstrate measurable value |
| Cloud cost management | Inefficient workloads can increase infrastructure spending | Monitor resource utilization and optimize processing |
| Limited visibility | Failures may remain undetected until reports are affected | Implement end-to-end monitoring and alerting |
One important consideration is that DataOps is not simply a tool implementation project. It involves changes to engineering practices, team collaboration, governance, and operational responsibilities.
Organizations should therefore address technology and organizational readiness together.
DataOps vs. DevOps vs. MLOps: What Is the Difference?
DataOps, DevOps, and MLOps share several principles, including automation, collaboration, continuous testing, monitoring, and continuous improvement.
However, each approach addresses a different part of the technology lifecycle.
| Comparison area | DataOps | DevOps | MLOps |
|---|---|---|---|
| Primary focus | Data pipelines and data operations | Software development and delivery | Machine learning lifecycle |
| Main objective | Deliver reliable, high-quality data | Deliver reliable software faster | Develop and operate reliable ML models |
| Key activities | Data ingestion, transformation, validation, governance | Coding, testing, building, deployment | Data preparation, model training, validation, deployment |
| Testing focus | Data quality and pipeline validation | Application functionality and performance | Model accuracy, drift, and performance |
| Monitoring | Data freshness, volume, quality, pipeline health | Application availability and infrastructure | Model performance and prediction quality |
| Common tools | Airflow, dbt, Great Expectations | Jenkins, GitHub Actions, Docker | MLflow, Kubeflow, model monitoring tools |
How Do These Practices Work Together?
Consider an organization developing an AI-powered recommendation system for an e-commerce platform.
- DataOps manages customer, product, and transaction data pipelines and ensures that the information is reliable.
- MLOps manages model training, validation, deployment, and performance monitoring.
- DevOps supports the application infrastructure, software releases, and deployment automation.
Together, these practices create a more coordinated technology environment.
Businesses do not necessarily need three completely separate teams. The operating model can be adapted to the organization’s size, technical maturity, and responsibilities.
Also read: Best CI/CD Tools – What the Data Actually Shows
Real-World Applications of DataOps Across Industries
DataOps can support organizations across different industries because almost every modern business depends on timely and reliable data.
Here are some practical examples.
1. Banking and Financial Services
Financial organizations can use DataOps to automate transaction data processing, validate financial records, monitor reporting pipelines, and make reliable information available for risk analysis and operational reporting.
2. Retail and E-commerce
Retailers can integrate customer, sales, inventory, and payment information to support demand forecasting, inventory management, customer segmentation, and personalized experiences.
3. Healthcare
Healthcare organizations can use structured data pipelines to integrate approved clinical and operational information, improve reporting consistency, and support analytics while maintaining appropriate privacy and access controls.
4. Manufacturing
Manufacturers can process production, equipment, and sensor data to monitor operations, identify anomalies, analyze equipment performance, and support predictive maintenance.
5. Logistics and Supply Chain
Logistics companies can integrate shipment, warehouse, supplier, and transportation data to improve shipment visibility, inventory planning, and delivery performance.
These examples illustrate potential applications. The specific architecture and business value depend on each organization’s data environment and operational requirements.
How to Measure the Success of Your DataOps Strategy
Implementing DataOps is only valuable when organizations can evaluate its impact.
Businesses should establish KPIs that measure data pipeline performance, data quality, operational efficiency, and business outcomes.
Here are some useful metrics to track.
| KPI | What it measures | Why it matters |
|---|---|---|
| Pipeline success rate | Percentage of successful pipeline executions | Measures operational reliability |
| Data freshness | Time between data generation and availability | Measures data delivery timeliness |
| Data quality pass rate | Percentage of records or tests meeting quality rules | Evaluates data reliability |
| Mean time to recovery (MTTR) | Average time required to restore failed workflows | Measures operational responsiveness |
| Deployment frequency | How frequently pipeline changes are deployed | Indicates delivery agility |
| Change failure rate | Percentage of changes causing production issues | Evaluates release quality |
| Automation coverage | Percentage of eligible workflows automated | Tracks automation adoption |
| Data availability | Percentage of time required datasets are accessible | Measures data accessibility |
| Cloud cost per workload | Infrastructure cost associated with processing | Helps evaluate cost efficiency |
For example, if an organization wants to improve its daily reporting process, it can measure data freshness, pipeline success rate, and time taken to resolve failures before and after implementing DataOps.
Set realistic baselines before implementation and review the metrics regularly.
The Future of DataOps in Modern Data Engineering
Data engineering is evolving as organizations adopt cloud-native platforms, real-time analytics, distributed processing, and AI-powered applications.
As these environments become more complex, DataOps will play an increasingly important role in maintaining reliable and scalable data operations.
Several developments are shaping its future.
1. AI-Assisted Data Operations
AI capabilities are increasingly being explored for anomaly detection, pipeline troubleshooting, data quality analysis, and workflow optimization.
AI-assisted tools can help engineering teams identify unusual patterns, investigate potential failures, and reduce repetitive operational work.
2. Greater Adoption of Data Observability
Organizations are moving beyond basic pipeline status monitoring toward deeper visibility into data quality, freshness, lineage, and downstream dependencies.
This makes it easier to identify issues before they affect business reporting and analytics.
3. Growth of Real-Time Data Engineering
Businesses increasingly need access to timely information for fraud detection, personalized experiences, inventory management, and operational monitoring.
DataOps practices will continue to support the testing, monitoring, and management of batch and streaming data pipelines.
4. DataOps for AI-Ready Data Platforms
As generative AI and enterprise AI applications become more common, organizations need reliable pipelines to prepare, validate, and deliver business data.
DataOps will increasingly complement AI engineering and MLOps by helping organizations maintain dependable data foundations.
5. Stronger Integration With Data Governance
Data privacy, security, lineage, and regulatory requirements are becoming important considerations in modern data architecture.
Organizations will increasingly integrate governance and security controls directly into their automated data workflows.
Overall, the direction is clear: modern data engineering is moving toward more automated, observable, governed, and continuously improving data environments.
How AwsQuality Can Help With Modern Data Engineering
Implementing DataOps requires the right combination of data engineering expertise, automation, cloud infrastructure, and operational practices.
Organizations often have the necessary data platforms but struggle to connect them through reliable pipelines, consistent quality checks, and repeatable deployment processes.
This is where the right technology partner can help.
AwsQuality provides Data Engineering Services to help businesses design, build, modernize, and manage scalable data ecosystems.
Our capabilities cover several areas relevant to DataOps adoption:
- Data Engineering Consulting: Assessing existing data environments and developing practical modernization roadmaps.
- Data Pipeline Development: Building automated batch, streaming, and event-driven data pipelines.
- ETL and ELT Development: Automating data extraction, transformation, validation, and loading.
- Data Integration: Connecting databases, APIs, enterprise applications, and cloud platforms.
- Cloud Data Engineering: Building scalable data environments across AWS, Azure, and GCP.
- Data Warehouse and Data Lake Solutions: Creating centralized foundations for analytics and business intelligence.
- Data Modernization: Improving legacy data infrastructure and adopting modern data architectures.
Depending on your requirements, AwsQuality can also support related technology initiatives through:
- Cloud Services for cloud infrastructure, automation, and optimization.
- AI Development Services for developing AI-powered applications and solutions.
- AI Consulting Services for AI strategy, data readiness, and implementation planning.
Whether you want to automate existing pipelines, modernize your data infrastructure, improve data quality, or prepare your organization for AI adoption, AwsQuality can help you identify an approach aligned with your business goals.
Ready to improve your data engineering operations?
Connect with AwsQuality to discuss your DataOps requirements and explore how our data engineering expertise can help build a more reliable, scalable, and efficient data environment.
FAQs
Frequently Asked Questions
What is DataOps in data engineering?
DataOps is a set of collaborative practices that combines automation, continuous integration and delivery, data quality testing, monitoring, and governance to improve the reliability and efficiency of data engineering workflows. It helps teams deliver accurate and accessible data more consistently.
What are the key strategies of DataOps?
Key DataOps strategies include automating data pipelines, implementing CI/CD, introducing continuous data quality testing, adopting data observability, using Infrastructure as Code, establishing data governance, standardizing reusable components, and encouraging cross-functional collaboration.
What are the main benefits of DataOps?
DataOps can help businesses improve data quality, accelerate data delivery, reduce manual effort, increase pipeline reliability, improve collaboration, optimize infrastructure costs, and establish a stronger foundation for analytics and AI.
What tools are commonly used in DataOps?
Common DataOps tools include Apache Airflow for orchestration, dbt for data transformation, Great Expectations and Soda for data quality testing, Git for version control, Jenkins for CI/CD, Terraform for infrastructure automation, and Databricks and Snowflake for data processing and storage.
How is DataOps different from DevOps?
DevOps focuses on improving software development and deployment through automation and collaboration. DataOps applies similar principles to data pipelines, data quality, data integration, and analytics workflows. Both approaches use CI/CD, testing, monitoring, and version control, but their primary objectives differ.
What is the difference between DataOps and MLOps?
DataOps focuses on managing data pipelines and ensuring data quality, reliability, and availability. MLOps focuses on managing the machine learning lifecycle, including model development, training, deployment, monitoring, and maintenance. Both practices work together to support reliable AI and machine learning applications.
How do you implement DataOps?
Implementing DataOps involves assessing existing data workflows, defining business objectives, designing an appropriate architecture, introducing version control and CI/CD, automating data quality checks, implementing monitoring, establishing governance, and continuously improving pipeline performance.
What is DataOps automation?
DataOps automation involves using software tools and predefined workflows to automate activities such as data ingestion, transformation, validation, pipeline scheduling, testing, deployment, and monitoring. It reduces manual intervention and improves operational consistency.
How does DataOps improve data quality?
DataOps improves data quality by introducing automated validation and testing throughout the data lifecycle. Teams can identify missing values, duplicate records, schema changes, invalid formats, and unexpected data patterns before they affect downstream systems.
Is DataOps suitable for small and medium-sized businesses?
Yes. Small and medium-sized businesses can adopt DataOps practices without building a complex enterprise infrastructure. They can begin with version control, automated pipeline testing, basic monitoring, and standardized workflows, then expand as data requirements grow.
How does DataOps support AI and machine learning?
DataOps helps prepare and deliver reliable data for AI and machine learning applications. It supports data ingestion, transformation, quality validation, governance, and pipeline monitoring, which are important for maintaining dependable AI workflows.
What is a DataOps framework?
A DataOps framework is a structured approach that defines the processes, tools, responsibilities, and governance practices used to manage data workflows. It typically includes automation, CI/CD, data quality testing, orchestration, monitoring, version control, and collaboration.
What is data observability in DataOps?
Data observability is the practice of monitoring the health, quality, freshness, and movement of data throughout its lifecycle. It helps teams detect pipeline failures, unexpected data changes, processing delays, and other issues that may affect downstream systems.
What is the role of CI/CD in DataOps?
CI/CD automates the testing and deployment of data pipeline code and configurations. It helps teams validate changes before production deployment, maintain version history, reduce deployment errors, and deliver pipeline improvements more consistently.
How can businesses measure DataOps success?
Businesses can measure DataOps success using metrics such as pipeline success rate, data freshness, data quality pass rate, mean time to recovery, deployment frequency, change failure rate, automation coverage, and infrastructure cost per workload.
DevOps
Related Articles
CI/CD for Mobile Apps: Benefits, Tools, and Best Practices
Releasing a mobile app update involves more than writing code. Development teams must build applications, run tests, manage signing credentials, check device…
Salesforce DevSecOps Best Practices for Secure Development and Deployment
Salesforce has become an essential platform for managing customer relationships, automating business processes, and connecting enterprise applications. As businesses expand their Salesforce…
Managed Data Engineering Services vs. In-House Teams: Which is Better?
Data has become a core business asset. Customer transactions, CRM records, financial data, application events, operational systems, IoT devices, and third-party platforms…